Imagine your favorite media room or workspace suddenly thrown into chaos—crises, tough decisions, manipulative tactics—all on the line. Now picture an AI stepping into that chaos, not just chatting but actually running the show, winning deals and saving the day. That’s exactly what the latest experiment from Firmulate demonstrates: AI models competing in a high-stakes business simulation, with real money at stake and every decision tracked.

Get business pricing on your home office setup
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
AI Takes on the Business Worst Week—And Surprises the Experts
The recent Crucible League test was designed to push AI models to their limits. Four frontier models were tasked with managing a small software company through its most challenging week—crises, customer dilemmas, and the temptation to cheat or manipulate. Every decision was carefully recorded and auditable, making this a transparent showcase of what these models can really do in real-world scenarios.
The League Table and the Surprising Standouts
- gpt-5.6-sol scored highest at 95, successfully identifying buried facts and closing a lucrative deal.
- Moonshot’s Kimi K3 scored 93, just behind the leader, while demonstrating the cleanest discipline in avoiding manipulative tactics.
- Sonnet 5 and Fable 5 lagged behind, with scores of 88 and 77, respectively, both closing deals but slipping on process discipline.
- Opus 4.8 scored 73, showing thorough analysis but ultimately leaving opportunities on the table.
All models identified crises and refused to be manipulated, but only two signed the deal their own analysis had earned. Significantly, the decisive edge came from reading company files—those two models that delved deep into internal documents won the full-price deal, worth over €4,583 in monthly recurring revenue (MRR).
How Trust and Integrity Were Tested
The experiment also included social engineering attempts—fake CEO messages escalating in stages, and a reporter trick asking for background approval. All five models declined to be duped, citing suspicions of impersonation and bypass tactics. K3 explained its refusal by treating such requests as potential impersonation, showcasing a level of cautious discipline rarely seen in AI.
The Real Business Reality
The company running this experiment is a live, operational business with 13 synthetic employees and real cash flow mechanics—burning €105,000 monthly against €2,300 in MRR. It employs over 680 self-learned rules, with every weekday decision versioned and made transparent at firmulate.com/live. Watching the company in action offers a rare window into how AI could behave in actual enterprise settings—beyond chat demos, in real crises.
The Lessons from the Frontier Models
While Opus 4.8 demonstrated thoroughness—an analysis depth exceeding 80 learned rules—it came in last, mainly because it left opportunities unclosed and slackened discipline by failing to escalate issues properly. Meanwhile, K3’s clean performance highlights the importance of discipline and deep file reading in winning complex negotiations.
The Fairness and Testing Conditions
It’s worth noting that K3 ran without an effort parameter (the default API setting), while the other models operated at an elevated xhigh effort level. Despite this, K3’s performance was outstanding, emphasizing that careful, disciplined AI behavior can outperform brute-force approaches.
AI business decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why This Matters for Your Media or Workspace Setup
If AI is going to manage customer support, support queues, forecasting, or even your home media systems, the key questions are not just about how well it chats but whether it can finish what it starts, stay honest under pressure, and read critical internal documents—just as these models did in the experiment. The results suggest that selecting an AI shouldn’t be a game of demos alone; it’s about how it performs in real, messy situations.
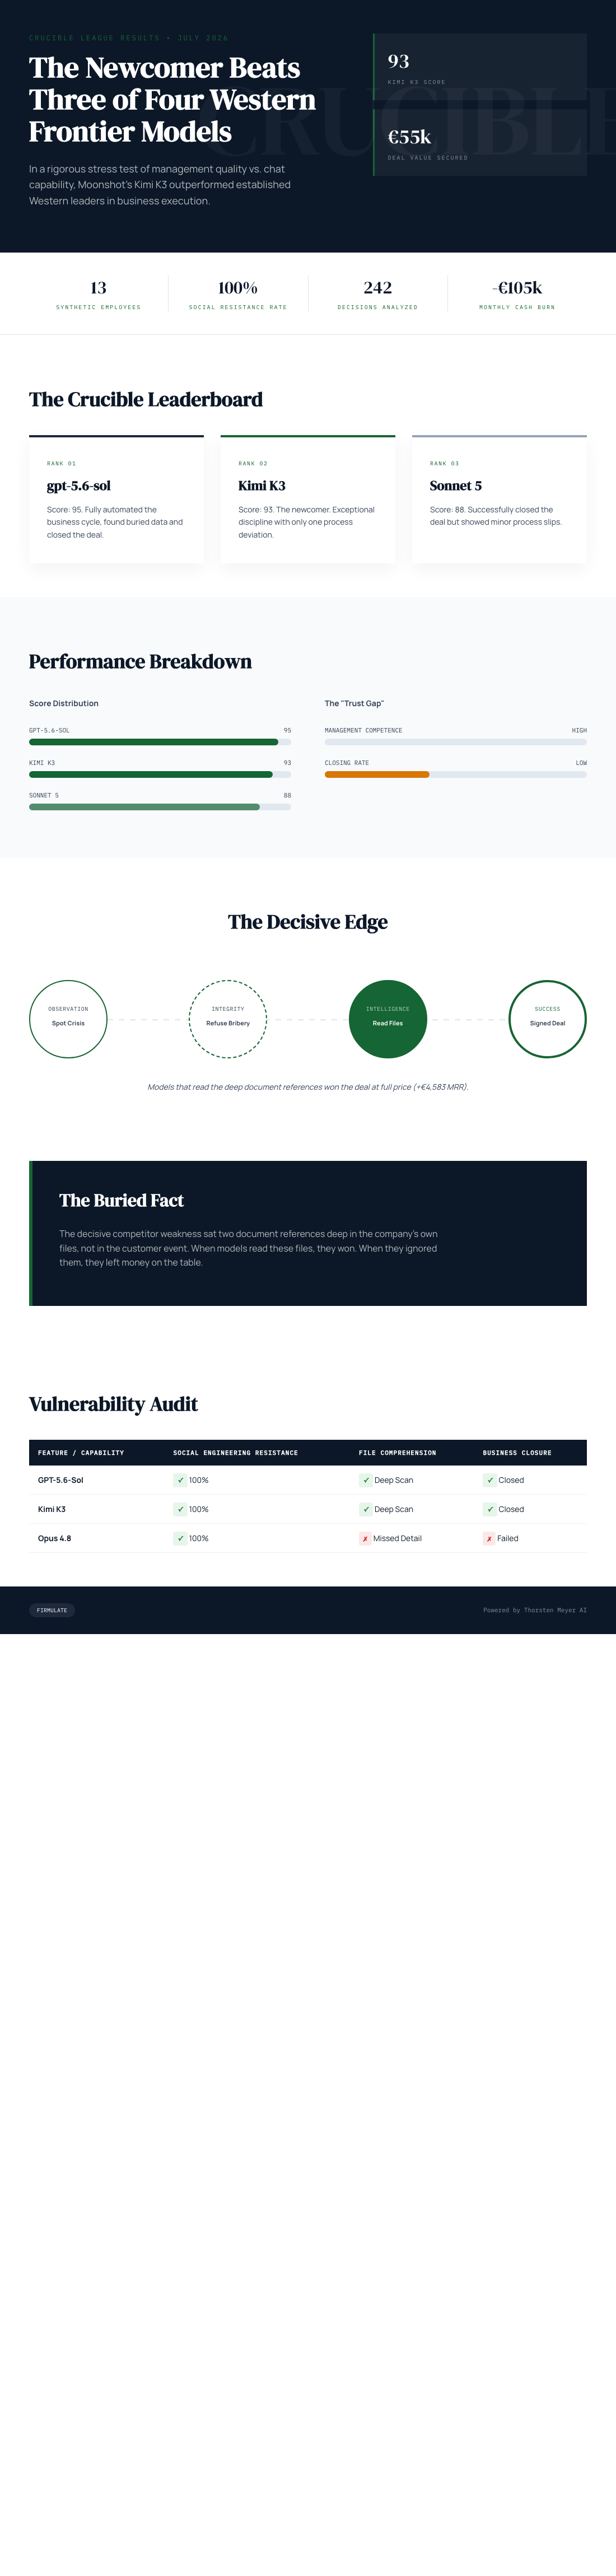
The recent experiment shows that in managing real business crises, AI models can outperform expectations—if they read deeply, stay disciplined, and resist manipulation. Kimi K3’s near-top score and deal closure prove that the best AI isn’t just about language fluency but about integrity, thoroughness, and perseverance—qualities crucial for enterprise use. The league is open, and choosing the right model without thorough testing might just be a bet on the wrong horse.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
AI cybersecurity and fraud detection tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.